
Free Stock Sentiment API
Sources, Limits & SetupStock Sentiment API
Sources & Setup
Compare signals, fields, limits, and validation before connecting stock sentiment to an app or agent.
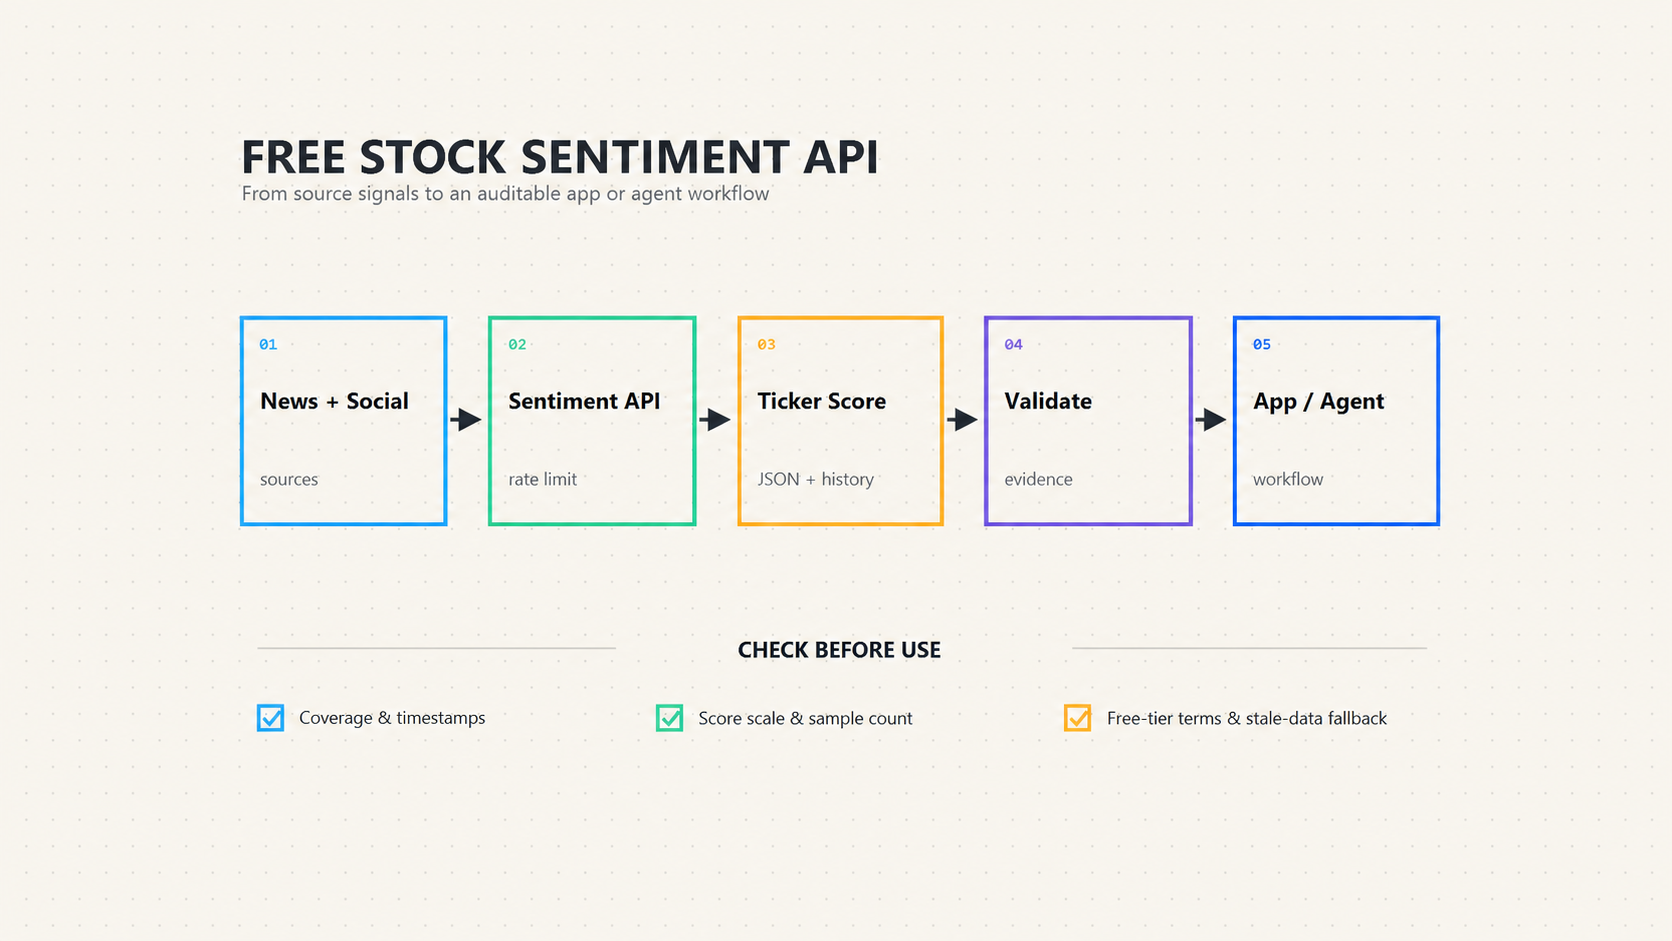
TL;DR
Developers want a working REST endpoint, a free key or no-key trial, ticker-level output, documented limits, and enough source context to judge the score.
News sentiment APIs score publisher coverage; social sentiment APIs aggregate Reddit, Stocktwits, X, or other communities. They are not interchangeable.
Check monthly calls, per-minute limits, delayed data, historical depth, commercial-use rights, supported exchanges, and attribution terms.
Treat sentiment as one input. Inspect source counts, timestamps, score scale, missing-data behavior, and revisions before using it in a workflow.
How to choose a free stock sentiment API
Choose the data source before comparing prices. A news-sentiment endpoint, a social-discussion feed, and a market-breadth indicator may all use the word “sentiment,” but they observe different behavior and answer different questions. Define the decision first, then evaluate whether the free allowance is sufficient for the required symbols, refresh rate, history, and evidence retention.
Match the source to the question
Use stock news sentiment data when you need publisher coverage tied to articles and timestamps. Use a Reddit stock sentiment API or broader social feed when you need retail discussion, mention volume, bullish/bearish labels, or buzz. For China-focused workflows, “market sentiment” may instead mean breadth, limit-up counts, consecutive boards, and risk appetite.
Provider routes to test first
The following services document sentiment-related endpoints, but they should not be treated as equivalent products or permanently free offers. Verify the current endpoint access, quota, market coverage, source licensing, and retention rights on the official documentation and pricing pages.
| Route | What it returns | Use it when | Verify before choosing |
|---|---|---|---|
| Alpha Vantage | News articles with ticker topics, relevance, and sentiment fields through its News & Sentiment function. | You want a documented market-data API family and article-level evidence for a prototype or scheduled brief. | Time range, ticker/topic filters, sort order, result limit, source coverage, delay, and current plan access. |
| Marketaux | Financial-news entities and sentiment fields that can be filtered by symbols, industries, countries, languages, and time. | Your workflow needs entity-level news context, multilingual filtering, and links back to the underlying articles. | Entity matching quality, duplicate stories, languages, historical reach, pagination cost, and rights to store article text. |
| Finnhub | A documented social-sentiment route for supported symbols, alongside company news and other market-data endpoints. | You need social activity and sentiment in a broader market-data workflow rather than article scoring alone. | Symbol coverage, source composition, update cadence, historical availability, field definitions, and plan entitlement. |
| Build from licensed raw sources | Your own item-level classifier, entity linker, deduplication, and aggregation over licensed news or community data. | You need transparent methodology, custom languages or taxonomies, and reproducible historical aggregates. | Source terms, deletion obligations, model evaluation, inference cost, moderation, and ongoing taxonomy maintenance. |
Check the free tier, not just the word “free”
| Criterion | What to verify | Why it matters |
|---|---|---|
| Sources | News publishers, Reddit, Stocktwits, X, or market breadth | Defines what the score actually measures |
| Coverage | Tickers, exchanges, ETFs, sectors, and delisted symbols | Prevents silent gaps |
| Limits | Calls per minute/month, concurrency, and caching rules | Determines prototype viability |
| History | Lookback window and point-in-time availability | Required for honest backtests |
Choose the signal by product workflow
Use article-level news sentiment with publication time, ticker relevance, source URL, topic, and a short evidence excerpt when licensing permits. Rank by relevance and recency, but show conflicting coverage instead of averaging every article into one apparently certain conclusion.
Track mention velocity, unique authors, engagement, bullish/bearish distribution, source concentration, and spam-filter rate. Separate popularity from direction: a sudden rise in mentions can matter even when positive and negative posts cancel to a neutral average.
Require point-in-time snapshots, stable source coverage, archived methodology versions, and an availability timestamp. Lag the feature to when it was actually observable, rebuild delisted-symbol history, and compare it against a simple price-and-volume baseline before claiming predictive value.
News or social NLP alone may miss the intended concept. Market breadth, limit-up and limit-down counts, failed breakouts, consecutive-board height, turnover, and index dispersion may be the more relevant inputs. Define the formula and trading calendar because “sentiment cycle” is not a standardized API field.
Stock sentiment API fields worth requiring
Minimum useful response
A practical response includes a normalized ticker, timestamp, sentiment label or score, score scale, source type, mention or article count, and a stable identifier. Confidence, source URLs, model/version metadata, and aggregation window make the output easier to audit.
Aggregation window and weighting
A daily score can be an equal average of articles, a mention-weighted social measure, an engagement-weighted index, an exponentially decayed signal, or the latest observation. Require window start and end, update cadence, weighting formula, minimum sample, source counts, and the treatment of missing periods. A score of 0.7 based on two posts is not equivalent to the same value based on 2,000 independent items.
Market-time alignment
Store the event or post time, provider ingestion time, aggregation cutoff, timezone, and whether the score belongs to premarket, regular trading, after-hours, or a 24-hour crypto window. Late-arriving articles must not be backdated into a decision bucket where they were not yet available. For cross-market studies, align local sessions before comparing sentiment with returns.
Historical stock sentiment data for backtesting
Historical data must be point-in-time safe. If an endpoint overwrites earlier values with revised aggregates, a backtest can accidentally see information that was unavailable at the time. Save the raw response, request time, provider timestamp, and version you actually received.
Validate the signal before using it
Create a dated benchmark with manually reviewed positive, negative, neutral, mixed, and irrelevant items. Measure ticker-assignment accuracy and score agreement separately from market prediction. Also inspect source concentration, reposts, bot or spam filtering, deleted-content handling, and the share of the score driven by a few high-reach accounts. Run the test again around earnings, quiet periods, and volatile sessions: a signal that looks stable in aggregate can fail when language is sarcastic, an article discusses several companies, or mention volume suddenly changes.
Normalize and validate stock sentiment scores
Provider scores cannot be merged safely until their meaning is explicit. One service may use −1 to +1, another 0 to 1, and another only bullish, neutral, or bearish labels. Even identical numeric ranges can represent different models, source mixtures, or time windows. Keep the original value and documented scale, then create a separate normalized field for cross-provider use.
Store the provider name, raw score or label, documented minimum and maximum, model or methodology version, item identifier, source URL when permitted, publication time, ingestion time, ticker relevance, and language. Never overwrite this layer when the normalization rule changes.
Choose an internal range such as −1 to +1 and map only documented numeric scales. Convert categorical labels through an explicit lookup table, not an assumed midpoint. Keep unknown, mixed, and missing separate from neutral; “no evidence” is not the same as balanced sentiment.
Wire stories, syndication copies, retweets, quoted posts, and near-identical headlines can make one event look like broad consensus. Deduplicate with stable IDs, canonical URLs, text similarity, source lineage, and a time window. Report both raw item count and effective independent-source count.
A passing mention should not carry the same weight as an article centered on the company. Apply documented ticker relevance, decay older observations, cap the influence of a single account or publisher, and require a minimum sample before publishing an aggregate. Return confidence or coverage separately from direction.
Freeze a dated set of earnings news, product announcements, litigation, analyst commentary, sarcastic social posts, multi-company stories, and irrelevant ticker collisions. Measure entity-link precision, sentiment agreement, duplicate reduction, coverage, latency, and revision rate. Only then test whether the signal adds value beyond price and volume features.
A production aggregate should explain itself. Return the normalized score together with the raw score range, window start and end, unique source count, total item count, dominant-source share, freshness, model version, and evidence links or IDs. An agent can then say “negative across 18 independent sources in the last six hours” instead of presenting an unexplained −0.63.
Free stock sentiment API setup for Python and agents
A safe four-step integration
Confirm authentication, symbol format, timezone, and empty-response behavior before batching requests.
Map the provider’s documented range to your internal schema; never assume that 0, 0.5, or “neutral” mean the same thing across APIs.
Store source URLs or identifiers, counts, timestamps, request parameters, and raw JSON alongside the derived value.
Respect rate-limit headers, cache only when terms allow it, and define what your app does when the feed is stale or unavailable.
Store permitted source evidence and normalized item-level scores before producing ticker aggregates. Version the aggregation code, weighting, model, and cutoff so a changed method can be replayed without losing the earlier approved signal.
Track score distribution, neutral share, sample count, source concentration, unmatched tickers, language mix, bot-filter rate, freshness, and revision frequency. Alert when the signal becomes constant, coverage collapses, or one source suddenly dominates.
Use QVeris to find and inspect stock sentiment APIs
QVeris can help an agent discover and inspect callable financial-data capabilities, then connect the selected tool to an auditable workflow. Provider availability, pricing, limits, and terms still need verification at call time.
- Open the Alpha Vantage News Sentiment tool details to inspect the exact capability.
- Review the QVeris REST API reference before connecting the capability to production.
- Keep provider responses and citations so an agent can show the evidence behind a sentiment summary.
FAQ
Is there a free stock sentiment API?
Yes. Some services provide a limited free allowance or evaluation access, but limits, history, source access, commercial rights, and maintenance vary. Verify the current pricing and documentation before choosing one.
Which API provides stock news sentiment data?
Several market-data and sentiment providers expose news sentiment. Compare whether the response includes article URLs, publication times, ticker relevance, score definitions, and historical access instead of choosing by the label alone.
Can I get Reddit stock sentiment through an API?
Some specialist APIs aggregate Reddit discussions and return ticker mentions or sentiment. Check subreddit coverage, update frequency, deleted-content handling, licensing, and whether raw evidence is available.
Can stock sentiment predict prices?
Sentiment may be a useful feature, but it is not a guaranteed predictor. Results depend on source quality, timing, market regime, methodology, and leakage-free validation.