
Build with a Free Earnings Transcript API
Compare transcript coverage, licensing, structure, and limits before turning quarterly calls into searchable research data.
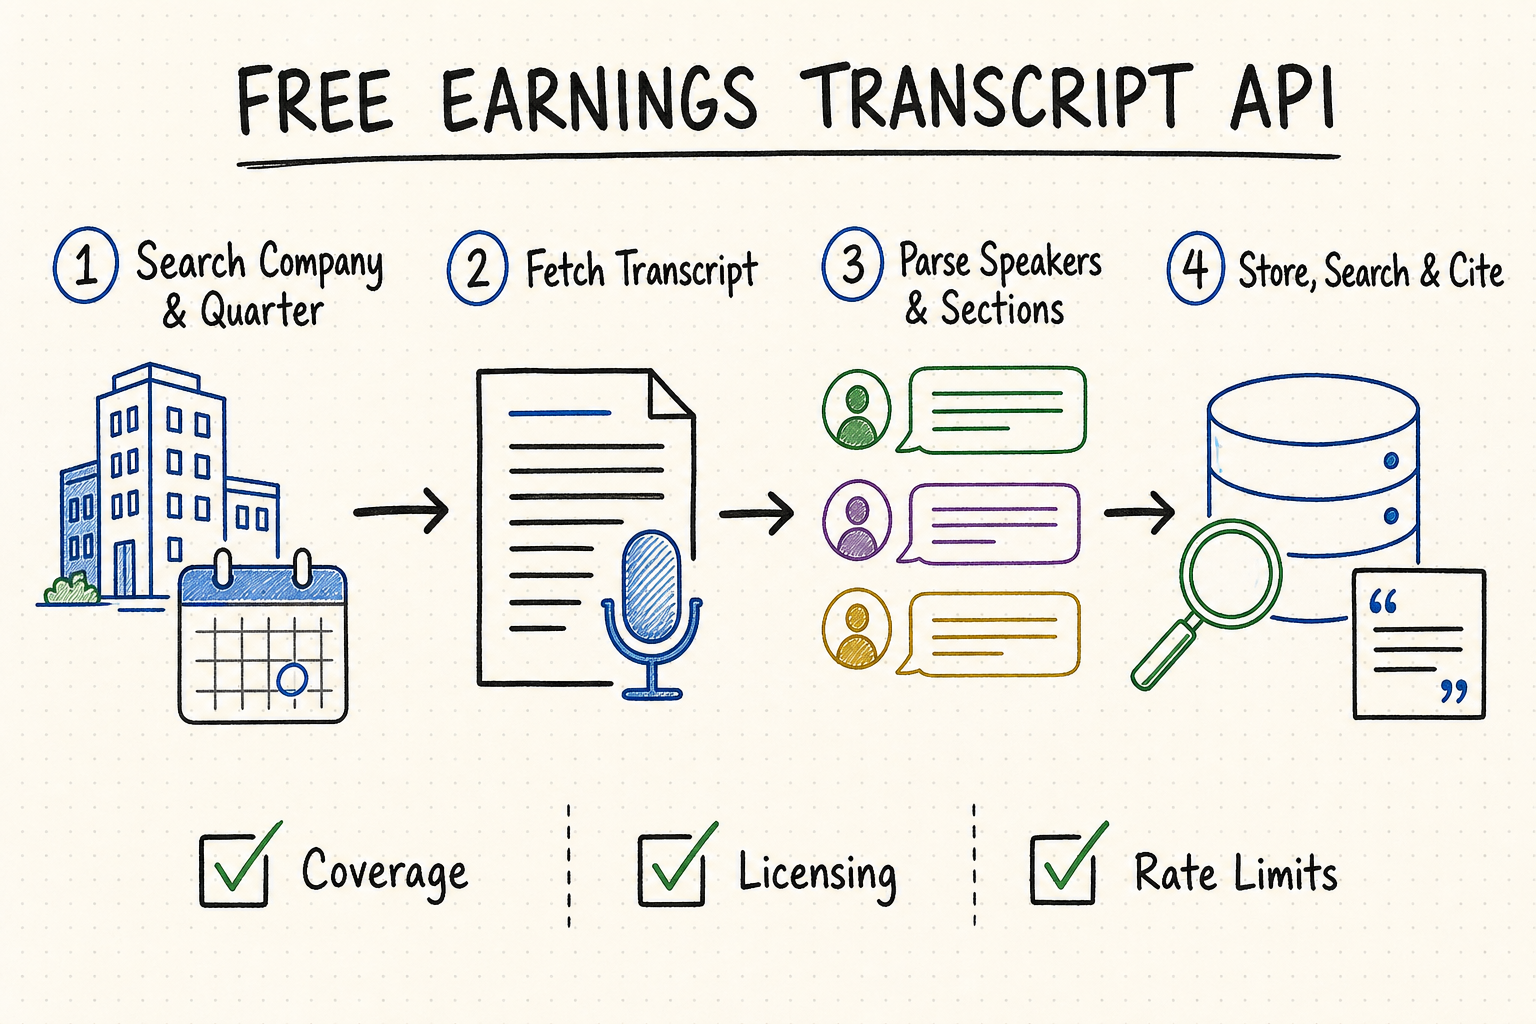
Core summary
A useful earnings transcript API returns more than a block of text. It preserves the event identity, company, fiscal period, call time, publication and revision times, prepared remarks, question-and-answer sequence, speaker names and roles, and a source record that supports quotation. For research and AI applications, every extracted claim should remain traceable to a specific speaker turn in a specific transcript version.
Look for prepared remarks, Q&A, speaker names, company, fiscal quarter, and publication metadata.
Free may mean a small quota, delayed access, limited history, or non-commercial terms.
Store raw text, normalized segments, source URLs, and retrieval times so quotations remain traceable.
Understand transcript coverage before choosing an API
Coverage differs by exchange, company size, language, event type, and age. Test whether the dataset includes special calls, investor days, guidance updates, merger calls, and corrected versions—not only scheduled quarterly results. Also distinguish an official transcript, a vendor-edited transcript, automated speech recognition, and an audio-only record; accuracy, publication speed, and quotation rights differ.
| Source type | What it is useful for | What must remain visible | Do not assume |
|---|---|---|---|
| Company-published transcript | Durable quotation and review when the company identifies it as the official record. | Publisher, event, publication time, revision notice, source URL, and any omitted portions. | That every company publishes one, or that the text is verbatim rather than edited. |
| Vendor-edited transcript | Structured speaker turns, normalized names, punctuation, and broad historical retrieval. | Vendor, edition status, edit time, speaker-resolution method, license, and correction history. | That edited wording exactly matches the live audio or can be redistributed freely. |
| Automated speech-recognition draft | Fast monitoring, event detection, and locating passages for later verification. | Preliminary status, model or provider, confidence where available, audio offsets, and replacement version. | That plausible names, numbers, negations, and speaker labels are correct. |
| Audio or webcast only | Primary evidence when access and retention rights permit independent transcription. | Event time, language, audio duration, access terms, retrieval time, and segment offsets. | That streaming access permits downloading, storage, transcription, or public quotation. |
Test large, small, delisted, renamed, and dual-listed companies. Verify stable company and event IDs, event type, fiscal year and quarter, call start time, timezone, and whether the event actually corresponds to the reported period.
Require prepared remarks and Q&A boundaries, speaker turns in order, executive and analyst roles, operator instructions, and paragraph or sentence offsets. Speaker labels should remain separate from the spoken text.
Measure call-to-first-text and call-to-final-transcript delay. A preliminary automated transcript may support same-day monitoring, while an edited or official version may arrive later and replace uncertain wording.
Check the original language, translations, punctuation, numbers, company and product names, acronyms, and speaker attribution. Test low-quality audio, overlapping speakers, and calls containing several languages.
Check whether corrections replace records or create versions. Preserve event time, publication time, update time, transcript status, source URL, and a checksum so citations do not silently point to changed text.
Evaluate a free earnings transcript API with real calls
| Test | What to inspect | Failure signal | Engineering response |
|---|---|---|---|
| Structure | Prepared remarks, Q&A, speaker role, sequence, and timestamps. | One unlabelled text block. | Create segments but preserve the raw response. |
| Identity | Stable company, event, quarter, and speaker identifiers. | Ticker-only matching. | Maintain an entity mapping table. |
| Text quality | Numbers, names, acronyms, punctuation, omitted audio, and confidence markers. | Plausible but incorrect words or figures. | Compare difficult samples with audio or an official source. |
| Versioning | Preliminary, edited, official, corrected, and translated versions. | Text changes under the same record ID. | Store checksums and retain prior versions. |
| Limits | Daily quota, burst rules, pagination, and retry headers. | Undocumented 429 responses. | Queue, cache, back off, and monitor quota. |
| Rights | Storage, analysis, quotation, redistribution, and attribution terms. | A free key with unclear license. | Block launch until rights are documented. |
Build a reliable transcript ingestion workflow
Resolve the company and earnings event, then query by stable event ID where possible. Confirm fiscal period, call time, timezone, event type, transcript language, and expected publication status.
Store the raw payload, request, source URL, retrieval time, status, version, and checksum before transformation. If audio is available and licensed, retain its reference for transcription review.
Record sections and speaker turns in sequence, keeping names, roles, offsets, and source text. Treat speaker resolution as a separate field so a later identity correction does not rewrite the quotation.
Chunk by speaker turn or coherent topic rather than arbitrary character count. Attach company, event, quarter, date, section, speaker, role, transcript version, and source offsets to every chunk.
Detect revisions with checksums, retain prior versions, rebuild affected indexes, and flag summaries whose cited source changed. Generated claims should quote sparingly and link back to the underlying turn.
Choose calls with prepared remarks, dense Q&A, unclear speaker handoffs, corrected numbers, product names, and forward-looking guidance. For each test, verify the quoted words, speaker, section, fiscal period, numeric unit, and source offsets. Score retrieval and extraction separately: finding the right passage does not prove that the generated claim preserved its meaning.
Consider a hypothetical call in which the CEO says during prepared remarks, “We expect next-quarter revenue growth of 10% to 12%.” In Q&A, an analyst asks whether that range includes a recently acquired business, and the CFO answers that the outlook includes two months of acquired revenue but excludes a possible currency headwind. A summary that stores only “guidance: 10%–12%” loses the scope conditions that make the number meaningful.
| Evidence unit | Store separately | Why separation matters |
|---|---|---|
| Prepared-remarks statement | Speaker, role, section, exact range, metric, target period, source offsets, and transcript version. | This is the initial guidance claim, not the complete set of assumptions. |
| Analyst question | Analyst identity, affiliation, question text, referenced claim, and sequence. | A question is context, not a fact asserted by management. |
| Management clarification | Responding speaker, acquisition treatment, currency assumption, confidence or uncertainty, and link to the question. | These qualifiers change how the numerical range should be interpreted and compared. |
| Derived research claim | Normalized metric, value range, period, scope flags, source turn IDs, extraction method, and review status. | Readers can verify both the headline number and the conditions attached to it. |
Revision rule: when a final transcript corrects “10% to 12%” to “10% to 11%,” create a new transcript version, link the changed turn, and mark dependent summaries for review. Do not rewrite the old record in place. Historical monitoring may need to preserve what was available at each publication time, while current research should normally point to the latest verified version.
Use QVeris to discover transcript capabilities
QVeris helps developers and agents find transcript, event-text, and corporate-call capabilities, inspect inputs and outputs, and make provider assumptions explicit before production use. It can simplify discovery and calling; the application still owns event identity, transcript versioning, speaker resolution, quotation rights, and the evidence attached to generated analysis.
- Search by capability, such as earnings transcripts, event text, speaker-labelled calls, or historical corporate events.
- Inspect authentication, identifiers, required parameters, response fields, pagination, and request frequency limits before integration.
- Keep a provider adapter and provenance trail even when discovery and calling are streamlined.
FAQ
Yes, usually with quotas, delay, limited history, or restricted usage rights.
Yes when licensing permits. Preserve citations and label generated summaries.
Cache raw responses and normalized segments; refresh metadata when corrections appear.
Keep the source label, normalized person ID, company or analyst affiliation, role, and confidence separately. Do not infer an identity from a surname alone when the quotation will be published.
Only if the license permits and the preliminary status is visible. Prefer the final or official version for durable research, and recheck citations when a corrected transcript arrives.
Start with speaker turns and section boundaries, then split only unusually long turns by topic while retaining source offsets. Arbitrary fixed-size chunks can separate a question from its answer.