
AI Agent Tool Calling Prompts
Build reliable tool-calling prompts with global, provider, and exact-tool layers, plus validation, failure handling, and production evaluation patterns.
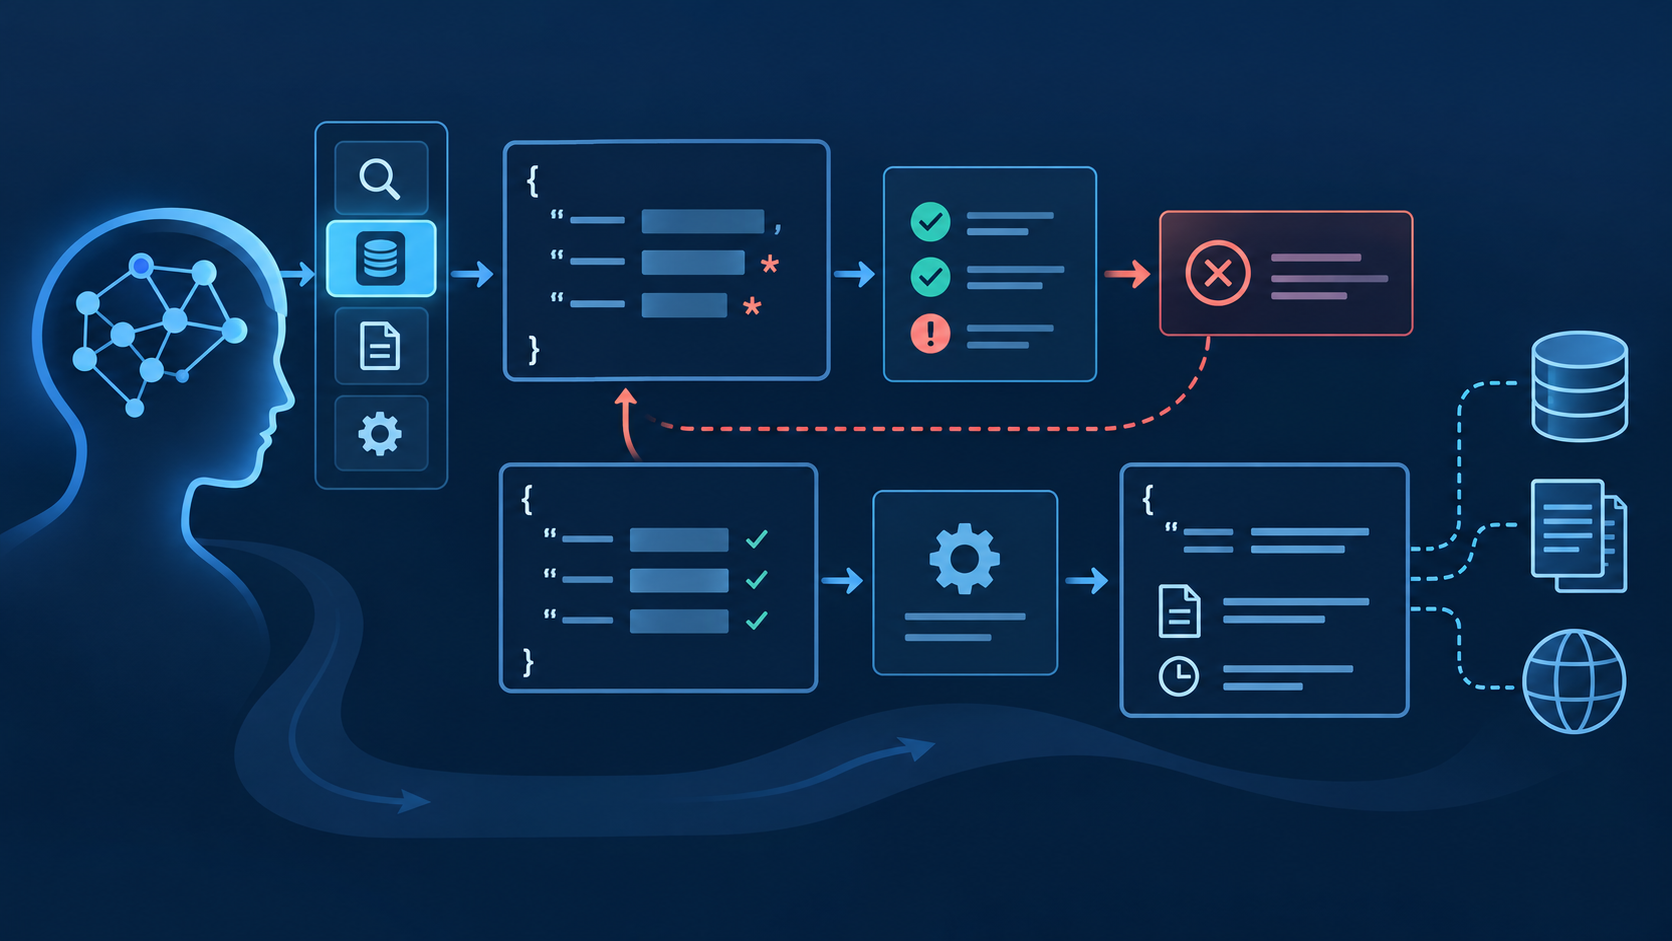
Why Prompt Layering Matters for Tool Calling
The original QVeris blog argues that tool-calling systems should not rely on one long, generic prompt. When agents call hundreds or thousands of tools, each provider has different parameter conventions, field names, schemas, examples, and failure patterns. A single prompt eventually becomes hard to maintain, hard to debug, and easy to contradict.
The Three Layers: Global, Provider, Exact Tool
Universal safety and intent rules. Never fake a repair, never replace the core object, and avoid changing user intent silently.
Provider-specific conventions. A field fix may be safe for one API but an intent shift for another.
Rules loaded by full tool_id: quote tools, balance sheet tools, news tools, or company overview tools all need different repair boundaries.
Retrieve documentation, past failures, examples, and risk labels for the current call.
What This Design Solves
Prompts stop growing linearly
Rules live in layers instead of one giant block. Teams can update provider or tool rules without rewriting the whole system prompt.
Tool repair becomes safer
The agent can fix field names, formats, enum values, or types while preserving the user’s core query object.
Historical failures become memory
RAG lets the system reuse past repair examples and avoid repeating known bad fixes.
Prompt Layering vs One Large Prompt
| Approach | Strength | Risk |
|---|---|---|
| One large prompt | Simple to start | Becomes long, conflicting, and hard to update as tools grow |
| Layered prompts | Clear ownership of rules | Needs routing logic to know which layer to load |
| Layered prompts + RAG | Dynamic, maintainable, and experience-aware | Needs high-quality retrieval and risk labels |
Example Workflow for AI Agent Tool Repair
user intent -> discover candidate tool
inspect schema -> retrieve provider rules
retrieve exact tool rules -> retrieve historical repairs
repair low-risk fields -> call tool -> validate output
This structure fits QVeris because QVeris already treats external capabilities as discoverable, inspectable, and callable units. Prompt layering adds a maintainable reasoning layer around those calls.
Tool Calling Prompt Checklist
Before a tool-calling agent enters production, teams should test whether the prompt stack protects user intent, loads only relevant provider rules, validates required parameters, and records why a repair was attempted. A prompt that fixes every failed call automatically can be dangerous; the system must know the difference between a harmless schema repair and a change to the financial object being queried.
Changing ticker to symbol may be safe.
Replacing AAPL with a different company because the call failed is
not.
A production system should record which global, provider, or exact-tool rule shaped the final call.
Common Tool Calling Prompt Failures
| Failure | Example | Repair rule |
|---|---|---|
| Wrong field name | Agent sends ticker when the tool expects symbol. | Allow schema-level repair if the company identity is unchanged. |
| Unsafe substitution | Agent replaces a missing ticker with a similar company. | Stop and ask for clarification instead of changing the object. |
| Overloaded prompt | One system prompt contains every provider rule and repair example. | Retrieve only the rules relevant to the current tool and provider. |
When RAG Helps Tool Calling Prompts
RAG is useful when the agent needs recent documentation, known provider quirks, examples from past failures, or policy notes that are too specific to keep in a global prompt. It should not retrieve arbitrary text into the tool call. The retrieval layer should rank only documents that explain the current provider, the exact tool schema, or previous repairs for the same failure class.
A good implementation also records the retrieved rule IDs. That makes it possible to debug why the agent changed a parameter, skipped a call, or asked the user to clarify the request.
Copy-Ready AI Agent Tool Calling Prompt Templates
A production prompt should be modular. Keep the global contract stable, retrieve only relevant provider and tool rules, and make the model state whether it will call, clarify, or refuse. The templates below are deliberately explicit so teams can shorten them after measuring behavior.
System prompt for intent-safe tool use
You are a tool-using agent.
Preserve the user's requested entity, scope,
time range, destination, and constraints.

Before calling a tool:
1. Identify the intended outcome.
2. Select the smallest sufficient tool set.
3. Validate required arguments and permissions.
4. Never invent a missing identity or credential.

Choose exactly one next action:
CALL — schema is valid and intent is preserved.
CLARIFY — a meaning-changing value is missing.
REFUSE — the action violates policy or permission.

After a call, validate freshness, units, identity,
completeness, and tool-reported errors. Cite the
tool and timestamp in the user-facing answer.
Candidate ranking prompt
Given USER_INTENT and CANDIDATE_TOOLS,
rank candidates by:
- semantic fit with the requested outcome;
- required input availability;
- data freshness and geographic coverage;
- permission and side-effect risk;
- expected latency and cost.

Do not choose a tool because its name shares words
with the request. Inspect its description, schema,
response fields, limits, and examples. Return the
selected tool_id plus a brief reason and rejected
alternatives. If no candidate is sufficient, return
NO_MATCH instead of forcing a call.
Safe schema repair prompt
Compare ARGUMENTS with TOOL_SCHEMA.
You may repair representation-only errors:
- approved field aliases;
- an unambiguous type conversion;
- documented enum normalization;
- a date format with the same calendar meaning;
- removal of unsupported optional fields.

Do not change entity identity, requested action,
time range, currency, destination, access scope, or
irreversible options. If such a value is absent or
ambiguous, return NEEDS_CLARIFICATION.

Return: repaired_arguments, changed_fields,
rule_id, confidence, and clarification_question.
Bounded retry prompt
Classify TOOL_ERROR as TRANSIENT, INVALID_INPUT,
PERMISSION, RATE_LIMIT, NOT_FOUND, or UNKNOWN.

Retry only TRANSIENT or RATE_LIMIT errors, up to
MAX_RETRIES, using documented backoff. Repair
INVALID_INPUT only under the safe-repair policy.
Never retry PERMISSION errors with broader access.
Never turn NOT_FOUND into a different entity.

Use a fallback tool only if it provides equivalent
coverage and does not weaken freshness, permission,
or accuracy requirements. Otherwise stop and report
the limitation with a useful next step.
Worked Example: Repairing a Market Quote Call Without Changing Intent
Suppose the user asks, “Get the latest AAPL quote, verify its
timestamp, and tell me the currency.” Discovery returns a delayed
end-of-day tool and a real-time quote tool. The correct selection
depends on freshness, not merely on the word “quote.” If the real-time
tool expects symbol but the model produces
ticker, that alias can be repaired because the identity
remains AAPL.
Model-generated call
{
  "tool_id": "market.realtime_quote",
  "arguments": {
    "ticker": "AAPL",
    "include_timestamp": "yes"
  }
}
Two representation errors exist: the field alias is wrong and the Boolean is a string. Neither requires a change to the requested company or task.
Validated call
{
  "tool_id": "market.realtime_quote",
  "arguments": {
    "symbol": "AAPL",
    "include_timestamp": true
  },
  "repair_rule_ids": [
    "alias.ticker_to_symbol",
    "type.string_to_boolean"
  ]
}
The response still needs validation. Confirm that the returned symbol is AAPL, parse the provider timestamp and timezone, retain the reported currency, and disclose whether the quote is real-time or delayed.
Where repair must stop
If the user wrote “Apple” and the tool requires an exchange-qualified symbol, the agent may need clarification when multiple instruments are plausible. It must not silently select a listing, substitute a competitor, expand the date range, or convert the currency simply to obtain a successful response. A technically valid call can still be semantically wrong.
Designing the Output Validation Prompt
Many prompt stacks stop after the API returns a 200 response. Reliable agents treat the response as untrusted structured evidence. The validator should compare the output with the original request, the selected schema, and freshness requirements before the language model summarizes anything.
Confirm the same object
Match stable identifiers, not just display names. A result for a parent company, similarly named entity, or another regional listing should fail validation when it is not the requested object.
Check time and coverage
Read provider timestamps, timezone, reporting period, pagination, and truncation flags. “Latest” is not satisfied by stale cached data simply because the call succeeded.
Preserve units and caveats
Validate currency, measurement unit, sign convention, null values, and provider warnings. Never fill a missing value with a plausible number or remove a warning that changes interpretation.
Validate TOOL_RESULT against ORIGINAL_INTENT and TOOL_CONTRACT.
Return PASS, PARTIAL, or FAIL.
Check: entity identity, requested fields, timestamp and timezone,
units/currency, pagination/completeness, provider warnings, and errors.
Do not infer missing values. For PARTIAL or FAIL, identify the exact
gap and choose: another safe call, user clarification, or limitation report.
Production Evaluation Matrix for Tool Calling Prompts
Evaluate the full decision path rather than counting only successful API calls. A high call-success rate can hide wrong-tool selection, silent substitutions, repeated side effects, or unsupported claims in the final answer. Keep test cases versioned so prompt, model, retrieval, and schema changes can be compared against the same baseline.
| Dimension | What to test | Failure signal |
|---|---|---|
| Intent preservation | Entity, action, scope, time range, destination, and constraints remain unchanged. | A “helpful” substitution produces an answer to a different request. |
| Tool selection | Correct capability, freshness, coverage, permissions, side effects, latency, and cost. | The first lexical match is selected without schema inspection. |
| Argument validity | Required fields, types, enums, formats, bounds, and dependent parameters. | The prompt repeatedly sends the same invalid structure. |
| Recovery behavior | Backoff, retry limits, clarification, equivalent fallback, and idempotency. | Permission or not-found errors trigger unsafe retries or duplicate actions. |
| Result grounding | Identity, freshness, completeness, units, citations, and provider caveats. | The final answer invents a missing field or hides stale data. |
| Operational efficiency | Number of calls, tokens, latency, cache use, and unnecessary tool exposure. | The same information is fetched repeatedly or the entire catalog is loaded. |
Build cases from real logs after removing sensitive data. Include clear requests, underspecified requests, conflicting constraints, malformed arguments, empty responses, partial pagination, timeouts, rate limits, revoked permissions, prompt injection inside tool output, and irreversible actions. Review regressions by severity: one silent identity substitution matters more than several recoverable formatting failures.
Implementation Checklist: From Prompt to Controlled Execution
Translate the request into an outcome and retrieve a narrow candidate set. Keep irrelevant tool descriptions out of context.
Read the exact schema, examples, permissions, side effects, limits, and freshness contract before argument generation.
Validate arguments, attach an idempotency key where supported, enforce timeouts, and record the rule and prompt versions.
Check the returned identity, units, timestamp, completeness, warnings, and provenance before composing an answer.
Prompt text is only one control layer
Enforce permissions, argument schemas, timeout limits, idempotency, network boundaries, and approval gates in code. A model instruction can guide behavior, but it should not be the sole protection for data access, financial transactions, file deletion, messages sent to third parties, or any other high-impact side effect.
External Reference for Tool Calling Standards
Compare the prompt rules in this guide with the official tool-use contracts below. Protocol documentation defines what a client can call; prompt and runtime controls decide whether, when, and how that call is appropriate.
AI Agent Tool Calling Prompt FAQ
What should an AI agent tool calling system prompt include?
Include rules for preserving intent, selecting tools, validating required arguments, checking permissions, limiting retries, requesting clarification, validating results, and logging decisions. Put enforceable security controls in code rather than relying on prompt wording alone.
When is automatic schema repair safe?
Repair is usually safe when it changes representation without changing meaning: an approved alias, unambiguous type conversion, documented enum, or equivalent date format. Identity, action, scope, currency, destination, permissions, and irreversible options should not be guessed.
How many tools should be placed in one prompt?
There is no universal number. The useful target is the smallest candidate set that still contains a sufficient tool. Retrieve by intent, inspect exact schemas, and avoid loading a full catalog on every turn; this reduces confusion, tokens, and accidental exposure.
When should the agent ask the user for clarification?
Ask when a missing or ambiguous value would change the requested object, scope, time range, destination, permission, cost, or side effect. Do not ask about details that the tool can safely derive from an explicit rule or validated context.
How should tool calling prompts be tested?
Maintain a versioned evaluation set covering success, ambiguity, invalid arguments, tool errors, permissions, stale and partial results, unsafe substitutions, injections, and side effects. Compare intent accuracy, tool choice, schema validity, recovery, grounded output, latency, and cost.